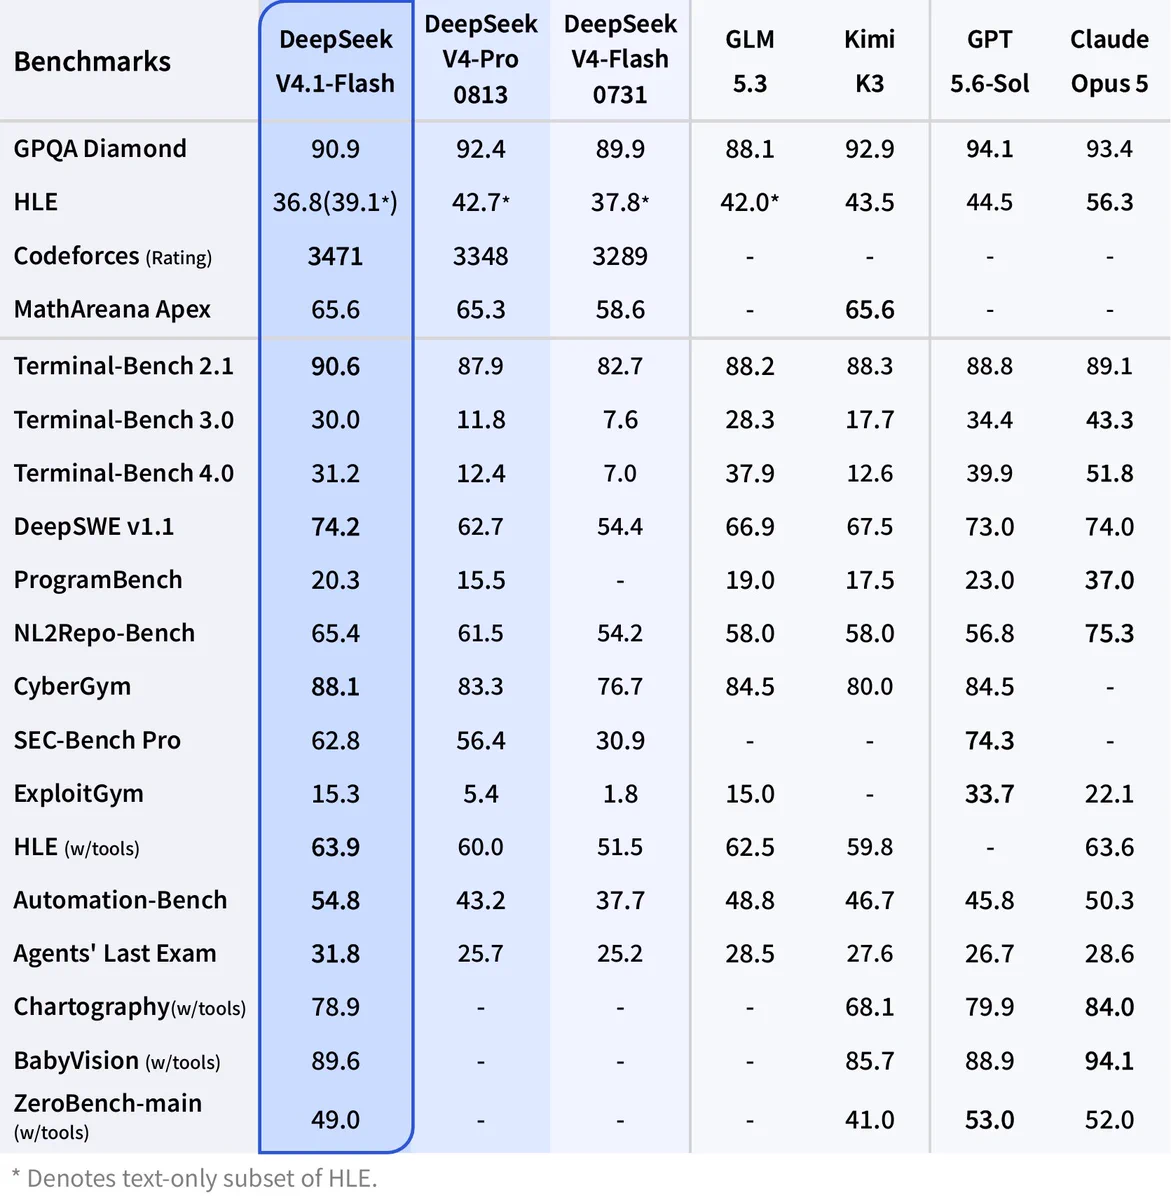
🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient.
🔹 Introducing the smallest model in our new architecture family, with native visual understanding.
🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
1/6
- 🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient. 🔹 Introducing the smallest model in our new architecture family, with native visual understanding. 🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models. 1/6
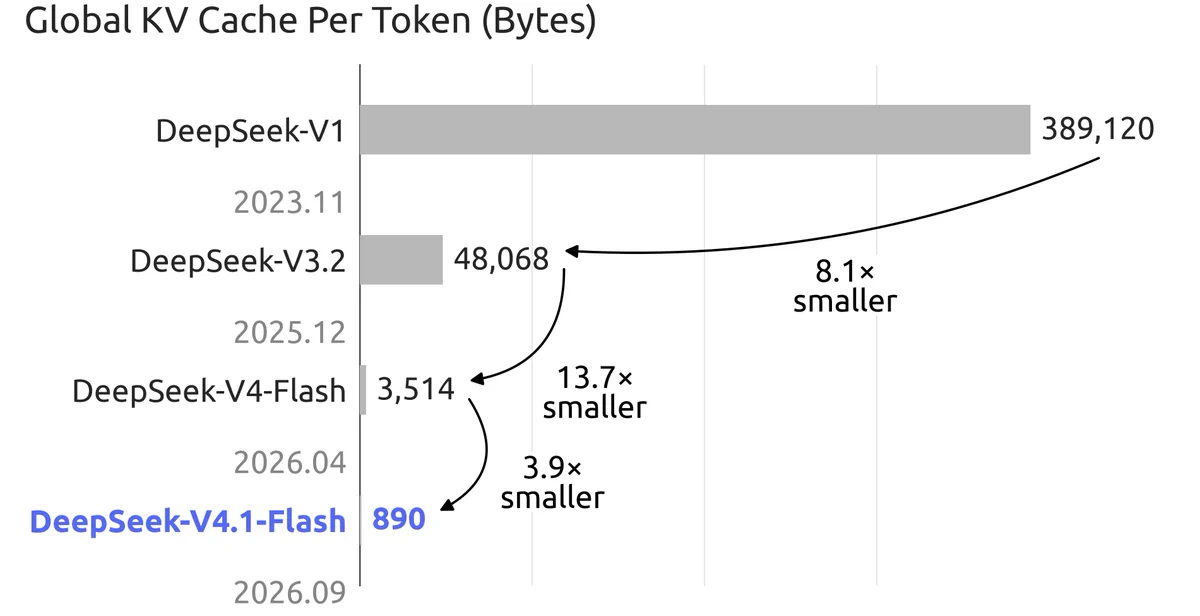
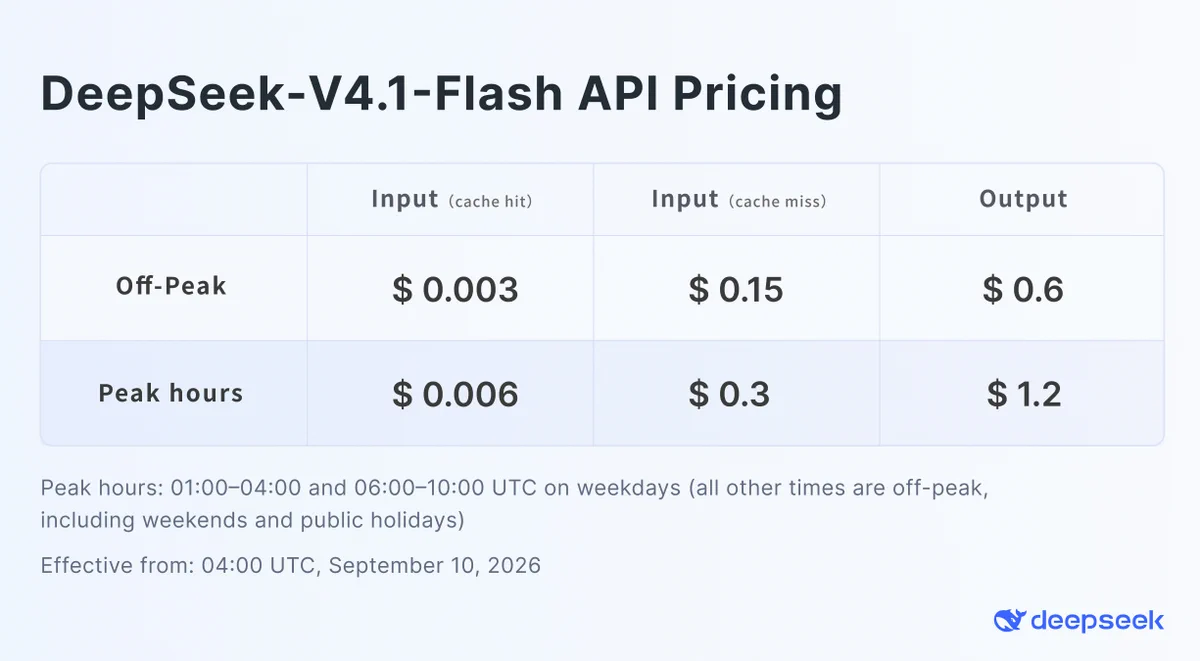
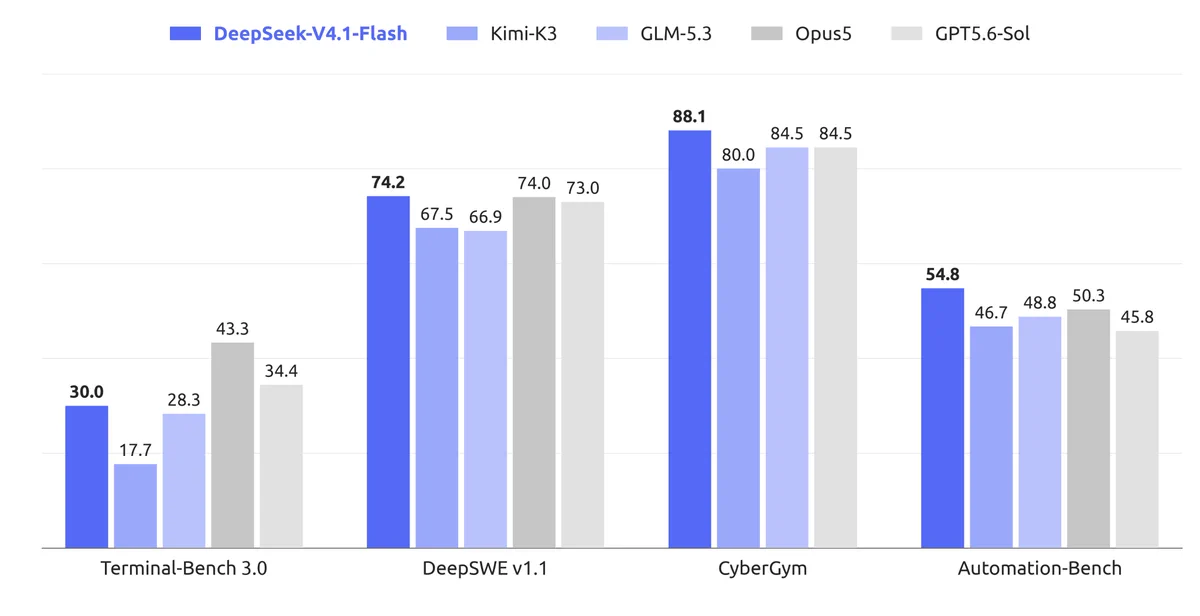
 🧠 Asymmetric architecture. More intelligence, less cost. 🔹 552B-parameter MoE. 🔹 New Causal Encoder–Decoder architecture: just 8B active parameters for input, 16B for output. 🔹 New pre-training methods + larger-scale RL post-training deliver benchmark results ahead of💾 Smaller KV cache. Bigger savings. Compared with the previous generation, V4.1-Flash’s KV cache needs just: 🔹 1/4 the HBM 🔹 1/8 the SSD storage Cache-hit charges often account for a large share of agent costs. Compressing the cache cuts those costs significantly. 3/6⚡ V4.1-Flash is now live on the DeepSeek API with native multimodal support. Set your model to deepseek-flash. 🔹 V4-Flash & V4-Flash-Vision-Exp are retired. For compatibility, deepseek-v4-flash and deepseek-v4-flash-vision-exp temporarily route to V4.1-Flash. 🔹 Tests by💰 More efficient architecture. Lower API prices. V4.1-Flash lets us serve more users at a lower cost. We’re passing the savings on to you. 🔹 Peak/off-peak pricing continues to balance demand. 🔹 Off-peak rates are 50% of peak rates. Schedule flexible workloads off-peak to🌐 Supporting open source. Expanding deployment options. We’ll work closely with the open-source community on V4.1-Flash inference support and explore more deployment options. Planning a large-scale deployment with 2,000 GPUs + a storage cluster? Let’s talk. 🔹 Model:
 Congrats DeepSeek on another epic release! Hopefully you guys will release smaller models for people to run locally. 🙏🐋 It's great that DeepSeek-V4.1 has 196B engram making it more accessible.